Summary
Scenario mining is the work of finding particular situations inside recorded logs after the fact, such as every night time encounter with a person walking near the shoulder. It exists because the events that decide whether an autonomous system is safe are rare, so a fleet records them incidentally rather than on purpose and has to go looking for them later. For [[Physical AI]] it matters because a situation nobody can retrieve cannot be counted in a safety case, weighted in a training mix, or turned into a test.
Scenario Mining: Definition and Scope
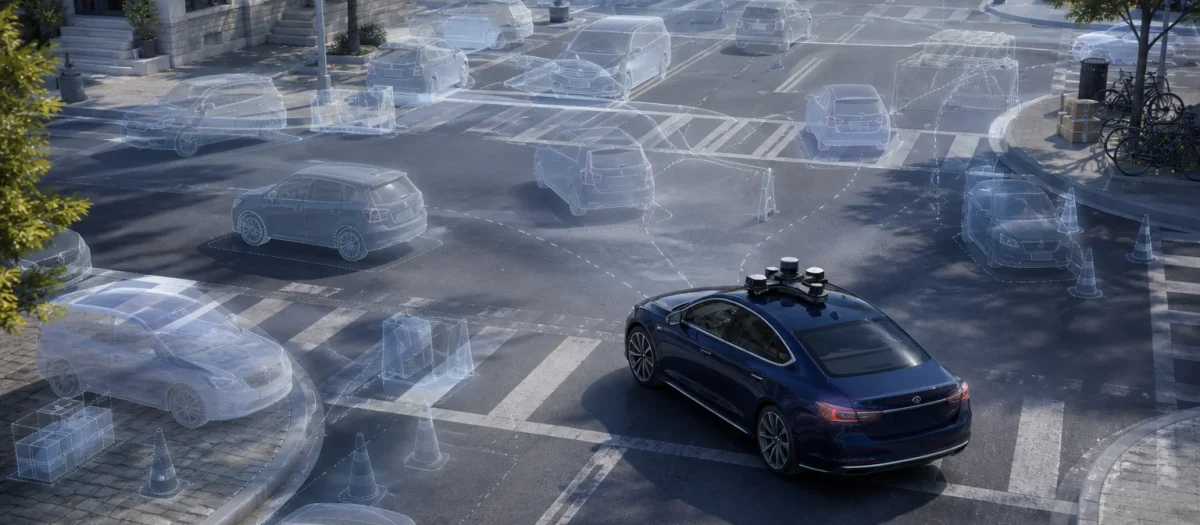
Scenario mining is retrieval over recorded operating data: given a description of a situation, return the logs, the time intervals, and the actors where it occurred. In the RefAV formulation, a method has to decide whether a described scenario occurs in a driving log at all and, if it does, localize it in both time and space with 3D tracks.
Two mechanisms are usually called by the same name and behave very differently. An event trigger runs on the vehicle at collection time and decides what to keep. A survey account describes Tesla’s fleet pipeline this way: a shadow-mode prediction that disagrees with the driver’s action, or a detected corner case, triggers a short snapshot upload, and the fleet is then searched for similar features. That description is secondary, built from public talks and reporting rather than a citable Tesla technical document, so the mechanism should be read as reported rather than as Tesla’s own specification. Offline mining runs over data already stored, so it can be re-run with a new definition, at the cost of only ever seeing what the trigger kept.
In scope for this node: taxonomy design, query construction, retrieval over stored sensor and track data, and the measurement of whether a query found what exists. Out of scope: scenario generation, which synthesizes situations rather than finding them, and the specification of an [[Operational Design Domain]], which states which situations are in bounds before any of them are recorded.
How Scenario Mining Works in Practice
Take a night freight corpus and a safety engineer who needs every instance of a person on foot near the travel lane in darkness, in order to state a rate for that situation.
The query runs over three things: the 3D tracks and their timestamps, the map layer that says where the lane edge and the shoulder are, and the taxonomy that says which combinations of those count as the situation. Methods differ in how the description becomes executable. nuPlan composes atomic primitives into SQL over a database, manually reviews 100 examples of each scenario type, and accepts low recall in exchange for precision across its 73 scenario types. RefAV instead has a language model synthesize a program from an API of atomic functions such as turning, accelerating and changing lanes. Either way the output is a list of triples: log identifier, start and end timestamp, and the identifiers of the actors involved.
Here is what goes wrong. The taxonomy boundary was never fixed, so one annotation vendor typed this situation as “pedestrian, roadside” and another as “vulnerable road user, ingress”. The query names one of those and silently returns a fraction of the events that exist. Nothing fails: the retrieval runs, results come back, and the count looks like a measurement. The team concludes the situation is rarer than it is, the next training mix underweights it, and the safety case rests on a denominator that was set by a labeling disagreement rather than by the road. This is the second failure the [[Autonomous Systems]] hub describes, and unlike a corrupt file it leaves no trace in the data.
A scenario type only records the situation the world presented; it says nothing about the outcome the system produced, and the same scenario type can end in several different entries in the [[Robot Failure Mode Taxonomy]], so a complete log needs both axes.
Use Cases
Safety case evidence. Assembling every occurrence of a named situation to state a rate. Production, and the reason regulators care: NHTSA’s AV framework notice of 31 July 2026 records 517 crash reports received under the Standing General Order between June and December 2025.
Training mix rebalancing. Finding under-represented situations and pulling more of them into the next corpus. Production.
Regression suites from real logs. Turning mined intervals into fixed test cases a stack version is re-scored against. Production, and the input side of [[Closed-Loop Policy Evaluation]].
Seeding simulation. Mined real situations become the parameter distributions synthetic variants are drawn from, which is the link between mining and [[Synthetic Data for Robotics]].
Natural language retrieval over sensor logs. Asking for a situation in a sentence rather than in code. Research stage: RefAV finds that off-the-shelf vision language models perform poorly at it.
Companies
Applied Intuition embeds fleet camera frames once upfront and serves natural language queries against those embeddings in its Data Explorer product. Production deployment.
Foretellix mines drive logs with Foretify LogIQ, decomposing matched scenarios into their sequential building blocks and extracting coverage metrics per match. Production deployment.
Motional built an internal pipeline to surface edge cases from annotated driving logs and feed them back into training and testing sets. Production deployment, and the same team behind nuPlan.
Datasets
Argoverse 2 Sensor supplies the 1,000 logs, HD maps and 10 Hz track annotations that the scenario mining challenge runs on.
RefAV adds 10,000 natural language queries over those logs, including 2,090 negative prompts, which is what makes a false positive measurable.
nuPlan publishes 73 mined scenario types with the query method and the manual QA procedure described.
SearchAD targets retrieval of rare images from large unlabeled driving corpora rather than spatio-temporal localization.
Papers
AutoMine Solution for AV2 2026 Scenario Mining Challenge, 2026. Notes that near synonyms such as passing and overtaking imply different conditions, and refines generated mining code against execution feedback from real logs.
SMc2f: Robust Scenario Mining for Robotic Autonomy from Coarse to Fine, 2026. Vision language filtering to localize time windows, then program generation, then contrastive re-ranking.
Foundation Models in Autonomous Driving: A Survey on Scenario Generation and Scenario Analysis, 2025, revised 2026. Surveys the generation and analysis literature the mining task sits between.
RefAV: Towards Planning-Centric Scenario Mining, 2025.
Coverage Metrics for a Scenario Database, 2024. Measures what a scenario collection actually covers rather than assuming it.
Towards learning-based planning: the nuPlan benchmark, ICRA 2024.
Software
ASAM OpenSCENARIO provides the scenario description language that mined situations are expressed in when they cross tool boundaries.
ASAM OpenLABEL standardizes how the objects and events inside a mined interval are annotated, and relies on ontologies such as ASAM OpenXOntology to keep their meaning unambiguous across tools.
Foretify Evaluate identifies scenarios in drive logs using OpenSCENARIO DSL alongside natural language search.
The RefAV method and its atomic function API are published as open source, which makes the program synthesis approach to querying tracks reproducible outside a vendor stack.
The nuPlan devkit stores each driving log as a SQLite database and exposes a scenario_filter interface that selects logs by scenario type and by log name, the query layer mining runs on when the underlying store is nuPlan rather than a vendor pipeline.
Logs captured at collection time are commonly written to [[MCAP]], the open source container format for timestamped multi-channel sensor and pub/sub data, rather than to a scenario-specific database; mining tools built against a fleet’s own log format query MCAP files directly.
State of Practice
ISO 34504:2024 defines scenario categorization for Level 3 and above driving systems as a set of tags carrying information about the scenario, with road user type at the top level, and it sits inside a family where ISO 34501 supplies the vocabulary and 34502 the evaluation framework. In the four major autonomous-driving datasets examined here—Waymo Open Dataset, nuScenes, Argoverse 2, and Zenseact Open Dataset—each taxonomy was developed within its program before ISO 34504 was published (Argoverse 2; Zenseact Open Dataset).
Where the field has not converged is on how well a query works. Published practice mostly optimizes precision and treats recall as secondary, which nuPlan states openly. RefAV is one of the few public measurements from the other direction, and its numbers are sobering. RefProg, the best performing method in that paper’s evaluation, reaches 64.8 HOTA-Temporal and 81.1 log level balanced accuracy when it runs on perfect ground truth tracks with no perception error at all, and drops to 50.1 HOTA-Temporal on the best predicted tracks tested. The 81.1 is a class-balanced score, averaged over logs that contain the situation and logs that do not, because the benchmark has far more positive than negative prompts. That figure comes from one benchmark over 1,000 short Argoverse 2 logs rather than from a general rate, and no comparable figure is published for a production pipeline.
The gap between literature and deployment is in what gets checked. Research benchmarks include negative prompts precisely so false positives are countable, and RefAV’s own construction required manual verification of every generated definition, where the authors found two recurring defects: relations reversed between the code and its description, and definitions that were underspecified, such as bicycles traveling against traffic without specifying the side of the road. Public disclosures reviewed for this note from Kognic, NVIDIA, Motional, and Applied Intuition did not establish recall, false-negative, or equivalent audit rates for production scenario-mining queries, so those query error rates remain unknown from the disclosures. This is the practical residue of the RAND 2016 finding that exposure alone cannot demonstrate reliability: a fleet driving more than 4 million autonomous miles a week, as Waymo reported in June 2026, converts a coverage problem into a retrieval problem.
Pain Points
Recall is unmeasured. A query returns results, so it looks like it worked. Establishing that it found most of what exists requires an independently labeled sample of logs that were not selected by the query, which is expensive and rarely done.
Taxonomy boundaries move. Two vendors, or the same vendor across a year, split a category differently, and the corpus quietly holds two definitions under one name.
Perception noise propagates. Mining runs on predicted tracks, and fragmentation, identity switches and heading error change what a motion predicate returns, which is what the RefAV gap between ground truth and predicted tracks measures.
Privacy and export. Fleet footage carries faces, plates and location traces of people who never consented to being recorded, and a mined clip set is exactly the subset most likely to leave the organization for annotation. Under the GDPR, carmakers processing this kind of footage for automated-driving development typically rely on Article 6(1)(f), the legitimate-interest ground, which requires weighing that interest against the recorded bystander’s rights rather than obtaining their consent; Toyota’s own privacy notice for its EU camera-based data collection names this basis explicitly. That balancing test, and any jurisdiction-specific export restriction on top of it, applies to the mined subset rather than to the corpus average, and a program outside the EU should confirm its own regime rather than assume this one.
Results are not reproducible. A query re-run after the taxonomy changed returns a different set, and without [[Dataset Provenance and Versioning]] there is no record of which definition produced the count in last quarter’s safety case.
Kotwel’s Role
Kotwel is the data-quality and data-operations partner for Physical AI. We turn multimodal physical-world and synthetic data into synchronized, structured, validated, and traceable datasets for training, evaluation, and continuous improvement. We make consequential data choices explicit and develop measurable quality criteria that enable organizations to benchmark and improve the data behind physical AI systems.
Scope and responsibility
Kotwel works at the data layer and remains independent of hardware, sensing architecture, and model family. We define data-quality criteria, audit datasets, and assess conformance against documented requirements. Clients retain control over program-specific conventions, intended model behavior, and operating requirements, provided those choices are explicitly documented and consistently applied. We do not build robots or autonomy stacks, develop control systems, or train foundation models. Decisions about system safety, legal compliance, and deployment remain with the client and its qualified advisers.
The specification stops giving one answer at a common trigger condition: a person standing beside a stopped vehicle on the shoulder, moving but not yet across the lane edge. One reading types the situation from intent, so it begins at the first movement toward the lane. The other types it from geometry, so it begins only when the body crosses the painted edge. Both are defensible, and they produce different data: the intent reading yields longer clips containing the approach, while the geometry reading yields a smaller set that begins at the crossing. They also produce different counts of the same road, which is what makes this a specification decision rather than a labeling error. Public work documents the same kind of failure: RefAV’s authors had to manually repair underspecified scenario definitions, such as a bicycle rule that did not state the side of the road, and the AutoMine report notes that passing and overtaking imply different conditions despite reading as synonyms. Kotwel operationalizes a client-defined taxonomy through event classification, annotation, and QA, writes the boundary cases into the specification before labeling starts, and measures agreement between annotators on scenario type rather than assuming it. Kotwel does not build mining infrastructure, retrieval models, or perception stacks.
Scenario mining returns the logs, time intervals and actors matching a described situation, and it is what makes a rare event usable after it has been recorded.
Collection time triggers and offline mining are different mechanisms: the trigger decides what survives, and offline mining can only ever search what the trigger kept.
The dominant failure is silent. An unfixed taxonomy boundary makes a query under-return, and the shortfall looks like a measurement of how rare the situation is.
ISO 34504:2024 standardizes scenario categorization through tags, but a program’s own taxonomy still has to be mapped onto it, and it is not established how many were designed that way.
Recall is the number almost nobody has. RefAV reports 64.8 HOTA-Temporal for RefProg, the best performing method in its own evaluation, running on perfect ground truth tracks, dropping to 50.1 on predicted tracks, and deployed pipelines rarely publish any equivalent figure.
Is scenario mining just search over video?
No, because the thing being searched for is usually a relationship between moving objects rather than an appearance. Frame level image retrieval finds a pedestrian; scenario mining has to find a pedestrian entering the lane ahead of the ego vehicle within a time window, which requires tracks, a map, and a definition of “entering”. This is why methods that classify individual image crops with CLIP style embeddings underperform methods that execute a program over tracks in the RefAV evaluation.
Can we just write the queries ourselves and skip the taxonomy work?
You can, and the queries will work until a second person writes one. A taxonomy is what makes two queries written months apart return comparable sets, and its absence is not visible in any single result. The cost shows up when counts from different periods or different vendors are put in the same table.
How do we know a scenario query missed something?
By labeling a random sample of logs that the query did not select, and checking how many of them contain the situation. Recall cannot be inferred from the returned set alone, because the returned set is defined by the query. Benchmarks with negative prompts, such as RefAV’s 2,000, make false positives countable in research settings; production pipelines usually have to construct the sample themselves.
Should we mine offline or trigger at collection time?
Use a collection-time trigger when storage or bandwidth constraints require deciding immediately what to retain. Use offline mining when retained data must be re-queried as definitions change or previously unanticipated situations become important. Use both when the program needs the storage control of triggering and the ability to revisit retained data with new questions.